• Skip to main content
Early Bird offer - - Ends 30th Sep - Book Now!

AutomationSTAR

Test Automation Conference Europe

  • Programme
    • AutomationSTAR Team
    • 2026 programme
  • Attend
    • Why Attend
    • Volunteer
    • Location
    • Get approval
    • Bring your Team
    • 2025 Gallery
    • Testimonials
    • Community Hub
  • Exhibit
    • Partner Opportunities
    • Download EXPO Brochure
  • About Us
    • FAQ
    • Blog
    • Test Automation Patterns Wiki
    • Code of Conduct
    • Contact Us
  • Tickets

Track Talk T4

Evals in Practice for an AI Coding Agent

Damián Pereira

11:00-11:45 CET, Thursday 5th November

Implementing an AI coding agent introduces a new quality challenge: while traditional unit, integration, and end-to-end tests ensure system stability, they do not adequately measure whether the agent produces the right code at the expected quality level.

This talk addresses that gap by focusing on evals as a practical, engineering-driven approach to validating an API Automation Agent that generates code from API specifications.

Rather than exploring eval theory, the session shows how real-world evals were designed and implemented to solve concrete problems such as validating generated files, grading test quality, enforcing architectural constraints, and detecting hallucinations or unsafe behaviors like prompt injection.

The talk explains how rule-based and model-graded evals were created, how they are executed, and how their results are interpreted to improve agent behavior over time. Attendees will leave with actionable guidance on when to use evals, how to design them for coding agents, and how to integrate them alongside traditional testing and benchmarks to build more reliable, secure, and quality-driven AI systems.

BACK TO PROGRAMME

What you will Learn

  1. Identify where evals add more value than traditional tests: Learn how to decide which parts of a coding agent should be validated with unit and integration tests, and where evals are the right tool to measure code quality, correctness, and safety.
  2. Design and implement practical evals for code generation: See concrete examples of rule-based and model-graded evals for a coding agent, including how they were created, what they measure, and how to balance determinism, cost, and signal quality.
  3. Run and interpret evals to improve agent behavior. Understand how eval results are analyzed, what a 'good' score actually means, and how findings are used to refine prompts, workflows, and constraints.

Session Details

  • Intermediate
  • 30 minutes
  • 15mins Q&A
  • Emerging Landscapes (Vibe Testing & Agentic AI)
Buy Conference Ticket

Session Speaker

Damián Pereira

Head of Testing - Endava, Uruguay

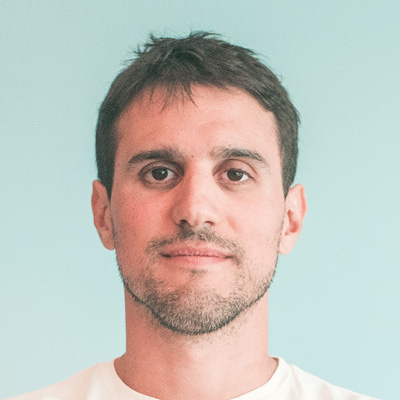
Damián Pereira is Head of Testing at Endava, leading a team of 50 testers and driving innovation in software quality and automation. With over 15 years of experience across testing, automation engineering, and leadership, he is passionate about combining technology and testing to empower teams. He has created open-source tools such as the API Automation Agent and TestCraft extension, and is an active international speaker. Damián has presented at QA or the Highway, TestingUY, and QualitySense Conf, covering AI in testing, automation strategies, and the evolving role of quality.
Stay in the Loop

Never miss important announcements, updates, and special offers from AutomationSTAR.

.

"*" indicates required fields

Send me more Information

Name*
GDPR*

Copyright © 2026 · Impressum · Privacy · T&C

part of the