A test suite goes green across the board. Every check passes, and the release ships to production. Then the support tickets start coming in: a regression got through, something the tests were supposed to catch. Nobody investigates too deeply, since it happened only once and could easily have been an isolated case.
Then it happens again. The same pattern repeats: a green suite, a real bug, and a gap nobody can explain. That is when teams finally start asking the question they should have asked from the beginning: did these tests ever actually work, or did they simply never fail?
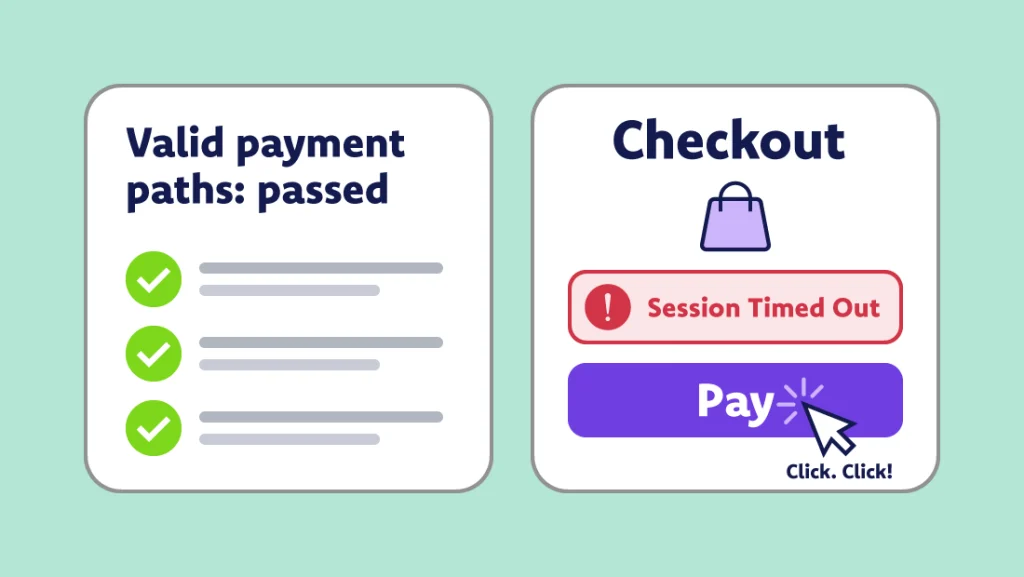
That question matters more now than it did two years ago because AI can write test cases in seconds, allowing teams to generate large numbers of tests in a fraction of the time. The problem is that teams can quickly end up with a suite full of tests that look thorough but fail to catch the bugs that matter. A green checkmark tells you that a test passed, but it says nothing about whether that test was ever capable of catching a real bug.
The AI doesn’t know your product, it’s guessing
An AI model writing a test case doesn’t know your product. It knows patterns. It has seen thousands of checkout flows, login forms, and API calls, and when you ask it to test yours, it draws on what those examples have in common. That’s often a reasonable starting point, since the basic structure of a checkout test is fairly predictable across products. But looking like a good test and actually checking the right thing are not the same, and the model has no way to tell the difference on its own.
Left unchecked, the model guesses. It might assert that a page loaded, that a field is not empty, that a button exists, none of which tell you the feature actually works the way your business needs it to. The test runs, returns green, and sits in your suite as false confidence.
Does this test actually earn its green checkmark?
Take a concrete case: an AI tool generates a test for a checkout discount code. The test enters a code, clicks apply, and checks that the page didn’t show an error. It passes. Should you trust it?
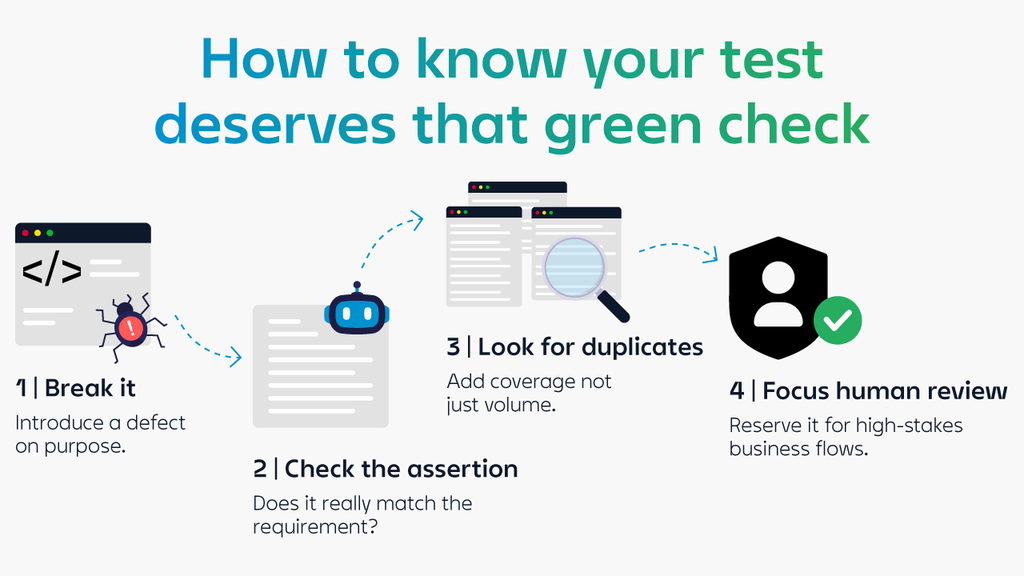
Here’s what actually you should do:
Break the code on purpose: this is one of the most reliable checks you can run, so it deserves close attention. Go into the discount logic and deliberately break it: make the discount apply twice, ignore the expiry date, or apply to an already-discounted item. If the test still passes after you’ve broken the logic it is meant to protect, it was never checking the right thing. This is called mutation testing. Instead of asking, “Does the test pass?”, it asks, “Can this test fail when it should?” Gartner recommends this approach for teams using AI to expand test coverage, since AI-generated tests can lack the depth needed to catch real defects on their own. In practice, you create several broken versions of the discount logic and check that the test catches each one. Any failure to detect a mutation tells you exactly what needs to be fixed before you can trust the green result.
Have a second AI model check the assertion: Once a test survives mutation testing, ask a different question: does its assertion actually match the requirement, or does it just confirm that something happened? For the discount code, the requirement isn’t simply that no error appears. It’s that the discount matches what the code entitles the customer to and that the order total reflects it correctly. A second model can compare the assertion against the written requirement and flag any mismatch. The goal is to close the gap between a test that confirms something happened and one that confirms the right thing happened.
Check for near-duplicates: AI tools generate tests quickly, but that can also mean generating the same test several times with small variations. If you already have four tests confirming that a discount code works correctly, a fifth that only changes the code string is not adding coverage. It is just adding another test to maintain. The ASTQB calls this “false confidence from volume”: a large test suite can look thorough while still leaving the same risks uncovered. Merge tests that overlap heavily and keep near-duplicates only when they cover a genuinely different path, such as combining a discount code with a gift card.
Save human review for what matters most: Not every test needs the same level of scrutiny. Sonar’s 2026 State of Code Developer Survey found that 96% of developers don’t fully trust AI-generated code to be functionally correct, while only 48% always check it before committing. The same caution should apply to AI-generated tests, particularly in areas where a failure can have a direct impact on customers and the business. Pricing, payments, and authentication deserve closer attention: a discount applied twice, a payment processed more than once, or a login that gives access to the wrong session can all have serious consequences. Reserve manual review for these high-stakes flows, while using mutation testing and AI-assisted review to validate the rest of the suite.
The next question testingON is built to answer
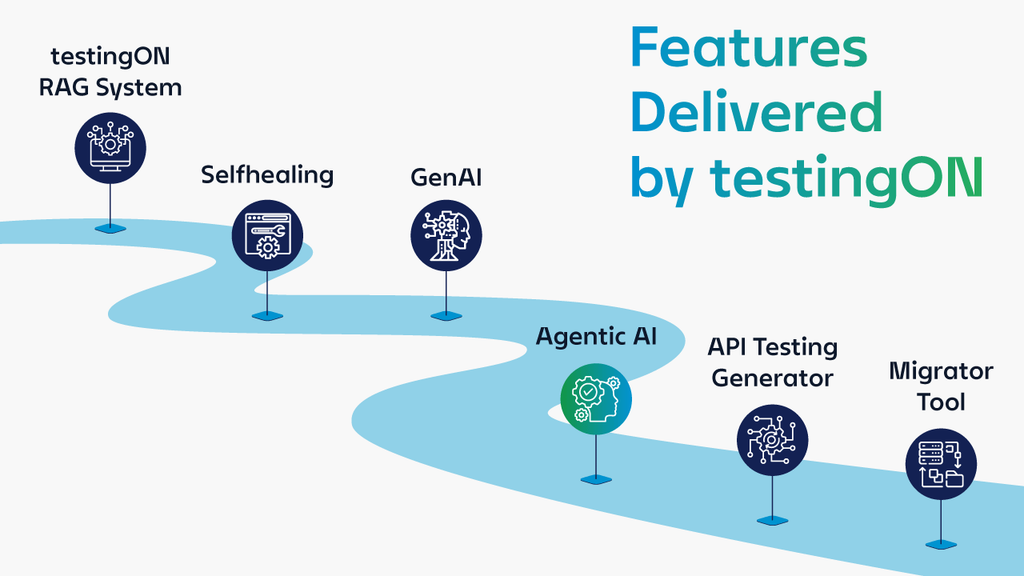
Most AI test-generation tools, including the ones enterprise QA teams are piloting right now, stop at generation. They write the test, hand it back green, and move on. They don’t run the checks described above, they don’t break the code on purpose, they don’t flag near-duplicates, they don’t know which paths are high-stakes enough to need a human. That’s true of most AI test-generation vendors too: speed is the pitch, and validation is left entirely to whoever’s using the tool.
We built testingON’s roadmap around closing that specific gap. Under an initiative we’re calling Agentic AI, we’re building an agent whose job is exactly what this post describes: taking a generated test and verifying it can actually catch a real defect, not just checking that it runs green. It sits alongside a companion agent that generates tests overnight against new user stories, and another that runs tests in the background and reports on execution results and performance, so generation, validation, and execution work as one connected process instead of three separate
tools bolted together. This is a roadmap direction we’re actively building toward, not a shipped feature today, but it’s a direct answer to the exact problem this post lays out.
If you’re piloting AI test generation and want to talk about how to validate what it’s producing before it reaches production, see what testingON is building.
Author
Tiago Honorato, Quality Management DevOps & Automation Associate Director at Noesis
I am a technology leader with more than 18 years of experience in Software Engineering, Quality Assurance, Product Innovation, and Digital Transformation.
I started my career as a Software Developer at Nokia Siemens Networks after completing my Master’s degree in Computer Science in Lisbon, Portugal. Shortly after, I embraced a new challenge at Noesis, where I founded and scaled the company’s Test Automation practice, helping clients accelerate their software delivery lifecycle and significantly improve quality standards.
Although I transitioned from development to Quality Assurance, I have always maintained a strong connection to software engineering — combining deep technical expertise with strategic quality vision. Over time, I led multiple initiatives across test automation, application development, and quality transformation programs for major enterprise clients.
Leveraging this cross-functional experience, I conceived and led the creation of testingON — a test management and automation platform designed to reduce testing time while increasing coverage and enabling non-technical users to actively contribute to quality processes. The platform integrates with leading test management, CI/CD, and project management tools and is currently used by major Telco, Retail, Banking, and Insurance organizations in Portugal and Brazil.
I later accepted a new challenge at NTT DATA, where I served as Senior Manager responsible for the Quality Assurance & Testing offering, leading strategic accounts, strengthening delivery capabilities, and expanding quality services.
Subsequently, I returned to Noesis as Associate Director to lead the strategic evolution of testingON. In this role, I am responsible for product vision, innovation roadmap, and growth strategy — including the integration of Generative AI capabilities and the modernization of the platform’s architecture to ensure scalability, cloud readiness, and long-term competitiveness.
testingON are Platinum Partners at AutomationSTAR Conference EXPO 2026. Join us in Antwerp 4-5th November 2026.