• Skip to main content
Don't miss out - Join us 4-5 Nov | Book Now!

AutomationSTAR

Test Automation Conference Europe

  • Programme
    • AutomationSTAR Team
    • 2026 programme
  • Attend
    • Why Attend
    • Volunteer
    • Location
    • Get approval
    • Bring your Team
    • 2025 Gallery
    • Testimonials
    • Community Hub
  • Exhibit
    • Partner Opportunities
    • Download EXPO Brochure
  • About Us
    • FAQ
    • Blog
    • Test Automation Patterns Wiki
    • Code of Conduct
    • Contact Us
  • Tickets

2026

Sep 10 2026

Six Test Automation Trends That Will Actually Change Your Week in 2026

What do this year’s conference submissions reveal about where test automation is heading? As a member of the AutomationSTAR 2026 Programme Committee, Gomathi Ramalingam has been reviewing the ideas and experiences practitioners want to share. Here, she picks out six trends that stood out—and offers a practical starting point for each.

You can join her tutorial, AI Testing Dojo: Build, Break & Master Agents, at AutomationSTAR 2026.

Every year someone publishes a list of testing trends, and every year most of it is weather. It rolls over the industry, makes a lot of noise, and leaves your Tuesday unchanged. So when we read through the AutomationSTAR 2026 submissions on the programme committee, I was looking for something different: not what people are excited about, but what is already altering the day-to-day work of the teams behind the submissions.

Two numbers stuck with me. Around two-thirds of this year’s abstracts mention AI, LLMs or agents in some form. And ‘trust’ turned up in roughly one in five, which is a vocabulary shift I have never seen at this scale before.

Put those together and you have the story of 2026: the industry has stopped asking whether AI will write our tests and started asking how on earth we know when it has done it well.

Here are the six trends I think deserve your attention, each with one thing you can start this week.

1. Agentic testing is moving from demo to duty

For the last two years, ‘AI in testing’ mostly meant a chat window that produced plausible-looking test cases. That picture is changing. The pattern now showing up in real pipelines is a set of specialised agents with narrow jobs: a planner that explores the application and drafts a plan, a generator that turns the plan into executable code, and a healer that re-runs failures and repairs broken locators.

Playwright has formalised exactly this planner–generator–healer split and the Model Context Protocol (MCP) has become the standard plumbing that lets an agent see an accessibility tree rather than a wall of raw HTML.

The reason this matters is that decomposition is a hallucination-control strategy. An agent with one small, checkable job is far easier to audit than a monolith that “does testing”.

Do this: Pick one narrow, boring job in your pipeline, such as triaging failed runs or proposing locator fixes and give it to an agent with a human approval step. Do not start with “generate our regression suite”.

2. Trust has replaced coverage as the metric that matters

The World Quality Report 2025–26 found that 89% of organisations are piloting or deploying GenAI in quality engineering, yet only 15% have managed enterprise-wide adoption. The most telling figure is the barrier list: 60% cite hallucination and reliability as a blocker. Teams are not short of AI-generated tests. They are short of a reason to believe them.

A green tick from a test the model wrote, asserting a value the model also invented, is not evidence of anything. I have watched a beautifully formatted suite pass at 100% because every assertion was tautological. The work of a tester in 2026 is increasingly to be the accountability layer for output that was produced faster than any human could read it.

Do this: Add a quality gate before AI-generated tests are merged. Mine has six checks, but even three will change your outcomes: does each test assert something the code could plausibly get wrong, does it reference a real endpoint or element, and would it fail if the feature were deleted?

3. AI-generated code needs AI-aware testing

It is not only tests being generated. A large and growing share of production code now starts life in a model, and the trust gap is widening: in Stack Overflow’s 2025 developer survey, 84% of developers use or plan to use AI tools, yet 46% say they do not trust the accuracy of the output, up from 31% the year before. That code has characteristic failure modes. It handles the happy path elegantly, invents APIs that do not exist, and quietly drops edge cases that were never in the prompt.
This is good news for testers. Classic technique is back in fashion. Boundary values, negative paths, state transitions and idempotency checks are precisely the things a model skips when it is optimising for “looks correct”.

Do this: When a change is flagged as AI-assisted, run a short, explicit review checklist against it rather than the same one you use for human code. The checklist should include “which inputs did the prompt not mention?”

Be in the room for all the important conversations at AutomationSTAR 2026 – book your tickets now.

4. Flaky tests are finally being priced

For years flaky tests were tolerated as a tax. This year’s submissions and blog posts treat them as a cost line, and that reframing is overdue. Every retry, every “re-run and it passed”, every engineer who has learned to ignore red builds is a measurable drain on delivery. And in an agentic world it is worse: an agent that learns your suite is noisy will learn to retry, heal and paper over, which is exactly the behaviour you do not want automated.

Do this: Spend an hour producing a flaky test audit. List the tests that failed and then passed on retry in the last thirty days, with the minutes of pipeline time they consumed. Take the number to whoever owns the roadmap. It is a far more persuasive argument than “we need to fix tech debt”.

5. API-first testing is the natural habitat for AI

There is a reason so much of the serious agentic work is happening at the API layer rather than the UI. APIs are text. Specifications are text. Requests and responses are structured, deterministic and cheap to run thousands of times. A model reasoning over an OpenAPI document is operating in its comfort zone; a model reasoning over a rendered DOM is guessing at pixels.
Contract testing fits this beautifully. A contract is a machine-readable statement of intent, which means it can serve as both the prompt and the guardrail for generated tests.

Do this: If you are going to let a model generate tests anywhere, start with your APIs, feed it the spec rather than a description and measure hallucination rate per prompt. You will quickly discover that some ways of asking produce reliable tests and others produce fiction. Keep a scored library of the ones that work.

6. The tester’s skill stack is shifting, and it is not towards prompting

The tempting conclusion from all of the above is that testers need to become prompt engineers. I do not think that is quite right. The skills the 2026 submissions actually reward are older and harder: writing precise context, designing an experiment that can distinguish a good output from a convincing one, and thinking adversarially about a system that will confidently tell you it is fine.
That is testing. It always was. The difference is that the system under test now includes the tool doing the testing.

Do this: Give your team a low-stakes sandbox and a challenge: build a small testing agent, then break it. Nothing calibrates judgement about where AI helps and where it is dangerously wrong faster than watching your own agent fail. It is the format I am using for a hands-on tutorial at AutomationSTAR this November, and it is the approach I would recommend whether or not you attend.

The thread running through all six

Automation has always been about removing humans from the parts of the work that do not need them. What 2026 is clarifying is which parts those are. Generation is being automated. Judgement is not. The teams that will do well are the ones that treat every green tick from an AI as a claim to be verified, not a result to be celebrated.

Want to take these ideas further? Join us at AutomationSTAR in Antwerp on 4–5 November for practical talks, hands-on tutorials and conversations with the people putting them to work. Explore the programme, and find the sessions that tackle your team’s next challenge. Check out and book your AutomationSTAR tickets.
Book tickets

· Categorized: AutomationSTAR, Uncategorized · Tagged: 2026

Sep 08 2026

When AI Can Generate the Tests, What Is QE For?

Ahead of her AutomationSTAR keynote, Quality Engineering Has an Identity Crisis… and AI Just Walked Into the Room, Laveena Ramchandani explores five skills that will matter more as AI takes on more of the mechanical work of testing.

Ask ten companies what Quality Engineering means today and you’ll get ten different answers – and at least three job titles nobody can properly explain.

That’s not a new problem. Manual testing became automation. Automation became Agile. Agile became DevOps. Each time, the job title changed and the core question stayed the same: what exactly are we here to do?

AI has just made that question urgent again. It can generate hundreds of test cases in seconds and produce dashboards that look impressively complete. What it can’t do is imagine a frustrated customer at midnight, trusting a product that quietly fails them at exactly the wrong moment. That gap between “the dashboard is green” and “the product is actually trustworthy” is where the next generation of QE skills live.

Here are five worth building now.

1. Judgment over green ticks

A passing test suite has never meant the same thing as a working product, but AI-generated coverage makes that gap easier to hide. When hundreds of test cases can be produced in minutes, the volume of green ticks stops being a reliable signal on its own.

Build it by: treating every AI-generated test suite as a first draft, not a final answer. Ask what it didn’t think to test, not just what it covered.

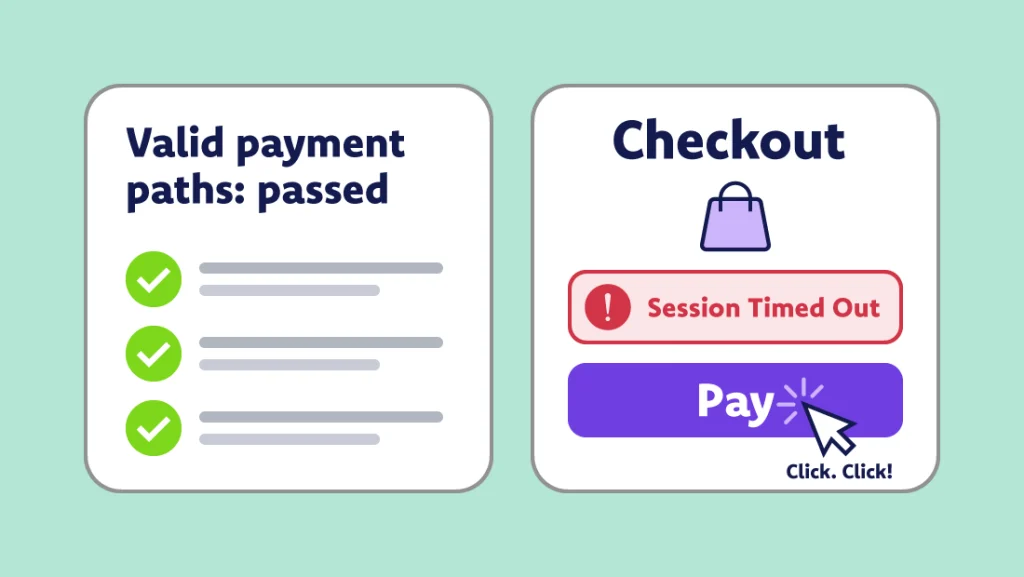
In practice: an AI tool asked to test a checkout flow generates 40 cases covering every valid payment path and misses the one where a user’s session times out mid-payment and they hit “pay” twice. Nothing in the spec says to test that. A tester who’s watched real users panic-click knows to check for it anyway.

2. Context engineering

AI can write a test. It can’t tell you whether the scenario it wrote actually matters to the business, the user, or the moment. That’s context and it’s a skill, not a byproduct of experience.

Build it by: getting closer to the “why” behind a feature before automation starts, not after. The best test ideas still come from understanding intent, not just reading a spec.

3. Trust architecture

As more of the pipeline becomes autonomous – self-healing tests, AI-generated cases, agents reviewing agents – someone has to decide how much autonomy each piece earns, and what happens when it’s wrong.

Build it by: mapping where in your pipeline AI output goes unchecked today, and deciding deliberately, not by default, whether that’s acceptable.

In practice: a self-healing test framework quietly updates a locator every time a UI element moves, so the test keeps passing. That’s useful until the element moved because of a genuine bug, and the “fix” just taught the test to ignore it. Someone needs to own the rule for when self-healing should stop and flag a human instead of patching around the problem.

Be in the room for all the important conversations at AutomationSTAR 2026 – book your tickets now.

4. Strategic questioning

The confidence to challenge what a machine confidently declares “complete” is becoming rarer than the ability to generate more tests. AI doesn’t hedge the way a careful engineer does; it states things as facts even when it’s guessing.

Build it by: practising the question “how do you know?” on AI output the same way you’d practise it on a stakeholder’s assumption.

5. Heuristic pattern recognition

This is the instinct that a system looks correct but still feels wrong – the thing that doesn’t show up in a test report because it was never written down as a rule. It’s built from exposure to failure, not from a framework.

Build it by: keeping a running list of the “something’s off” moments you notice but can’t yet articulate: a response that’s technically correct but feels wrong, a flow that passes every check but still confuses you. Revisit the list monthly. They’re usually the first sighting of a pattern worth naming, long before it becomes a rule anyone could write down.

Finally, none of these are new instincts; testers have always needed them. What’s changed is that AI has taken over the mechanical parts of the job fast enough to make the human parts visible by contrast. The tools will keep changing. The people who understand risk, context, and human impact are the ones who don’t become replaceable by the next one.

Check out the programme to see Laveena’s keynote, and book your AutomationSTAR tickets.
See tickets

· Categorized: AutomationSTAR · Tagged: 2026

Sep 07 2026

The Keyword Is the Contract

How the right layers of abstraction improve collaboration, maintainability and technical flexibility

Open a test specification and you read: the customer places an order. Open the automation for the
same test and you find forty lines of selectors, waits and assertions. Both claim to describe one test.
Three sprints later a checkout step has moved, someone patched the code but not the specification,
and nobody can say which one is still true.

Anyone who has maintained a test suite for a year knows the situation. It isn’t a communication
problem. It’s a missing interface.

The people best placed to decide what to test are usually not the people who can automate it.
Business testers understand processes, requirements and the scenarios that matter. Automation
engineers understand frameworks, interfaces and the technical details of the system under test.
Traditional automation puts the two groups in a relay race: first specify, then automate. Every
change to the specification means a change to the code, and unless someone keeps paying the
manual cost of alignment, the two artifacts drift.

That drift was survivable when releases came quarterly. At weekly, it isn’t. Cycles get shorter,
expectations keep rising, and a specification nobody trusts stops being documentation and becomes
a liability.

More discipline won’t fix it. Abstraction will, applied in more places than most teams think.

Why Abstraction

Clean code has a rule for it: single level of abstraction. A function works on one level of detail instead
of mixing business logic with string handling. What you get is readability, understandability,
maintainability and reuse. Testing can borrow the principle, and two standards tell you where to put
it.

Abstraction 1: The Test Automation Architecture

ISTQB’s Generic Test Automation Architecture, laid out in the CTAL-TAE syllabus, applies the same
idea to the automation solution and separates four layers:

  • Test generation — designing test cases, deciding what to test
  • Test definition — test suites, test cases, test data, the reusable keyword library
  • Test execution — the engine that runs the tests, logs and reports
  • Test adaptation — the code that talks to the interfaces of the system under test

What makes the model useful is the separation it enforces. A change in one layer rarely forces a
change in another. A re-labelled button hits the adaptation layer, not two hundred test cases. Swap a UI-driven check for an API call on the same business step and the test definition layer never notices. The layers tell you where the boundaries belong, not how an intent stated at the top arrives as
executable code at the bottom.

Abstraction 2: The Test Specification

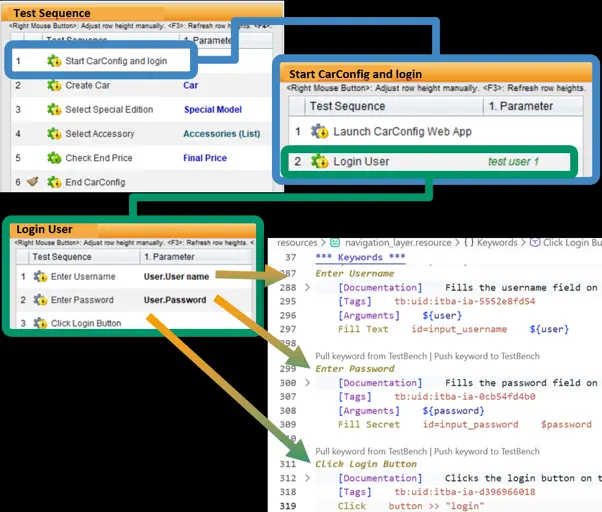
Keyword-driven testing is the answer. ISO/IEC/IEEE 29119-5 describes keyword-driven testing, and
the second edition from 2024 is explicit about hierarchy. At the bottom sit generic technical
keywords such as “Click” , “ Fill Text ” or “Get Element States ” . Those get composed
into business-level keywords: “ Log in as a registered customer ” , “ Place an
order ”
. A test case is then a sequence of business keywords plus test data, readable by anyone
who knows the domain, with no code in sight.

The hierarchy itself isn’t the most interesting part. What it produces is a contract. The keyword name
and its parameters are the interface between the two worlds. A business tester can reorder steps,
add a data variant or build a new test case from existing keywords without touching automation
code. An automation engineer can rewrite whatever happens behind “ Place an order ” , new
UI, new API, new library, without invalidating a single test case. Each side changes what it owns. The
artifacts stay aligned because the thing that matters exists only once: the keyword.

Abstraction 3: The Tooling

Here is the step most teams skip. If the layers really are separate, no single tool must cover all of
them. That matters, because the two groups don’t want the same tool. Ask a business tester to
specify tests in VS Code and you lose them; an IDE isn’t their workplace and Git isn’t their
vocabulary. Ask an automation engineer to implement technical steps by clicking through a GUI and
you take away autocompletion, refactoring, version control and code review, which is most of what
makes engineering possible.


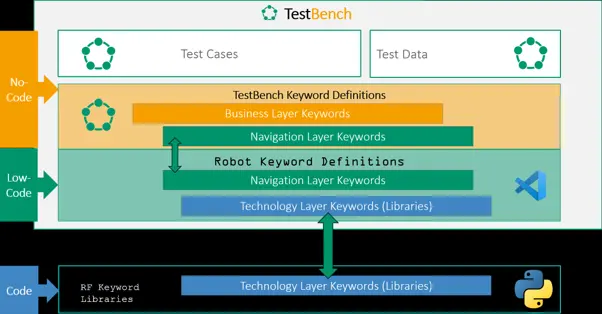
So choose per layer, then connect the layers. In our case, TestBench covers test definition, entirely
no-code: business testers maintain keywords and test data in a GUI and assemble test cases from
them. Robot Framework and VS Code cover the implementation, low-code where the existing Robot
Framework libraries suffice and real Python in user keywords where they don’t.
testbench2robotframework generates Robot Framework suites from a TestBench report and writes
the results back, and the TestBench extension for VS Code keeps keywords, descriptions and test
data in sync.

29119-5 expects this. The standard defines requirements for a common data exchange format so
that tools from different vendors can hand test cases, keywords and test data to each other.
Exchanging artifacts between tools isn’t a workaround for the all-in-one product nobody sells; the
standard treats it as the normal case.

Where It Breaks

Abstraction isn’t free. Keyword libraries grow, and an unmaintained catalogue of hundreds of nearidentical keywords is worse than none: nobody finds the right one, so everybody adds another.
Keywords cut too finely (Click button, Enter text) push technical detail straight back into the test
specification and cancel out the benefit. Layers hold only if someone owns the keyword library, if
naming conventions are agreed and enforced, and if keywords get reviewed as seriously as code.
Standards hand you a structure. Nobody hands you the discipline to keep it clean.

What You Actually Gain

Two things. A shared artifact that a business tester can read and an engineer can execute. And, less
obviously, a shared vocabulary. Domain-driven design calls this a ubiquitous language: one rigorous
set of terms used by domain experts and developers alike, in conversation and in the code. Keyword driven testing produces exactly that as a by-product. When “Place an order” means the same thing in a review meeting, in a test case and in a Robot Framework keyword, the two groups have stopped translating between worlds. They are editing the same sentence.

Further Reading

Leave Complexity Behind: No-Code Test Automation with Low-Code integration via Robot Framework and TestBench

Author

Falk Altrock, Product Owner TestBench
imbus AG

TestBench are exhibitors at AutomationSTAR Conference EXPO 2026. Join us in Antwerp 4-5th November 2026.

· Categorized: AutomationSTAR · Tagged: 2026, EXPO

Aug 31 2026

The Flaky Test Audit: What Your Suite Really Costs You

A flaky test passes and fails on the same code. Same commit, same environment, nothing changed. Run it ten times and you’ll get eight passes and two failures.

That inconsistency makes it worse than an ordinary failure. A real failure tells you something is broken. A flaky failure tells you nothing: you can’t say whether you found a bug or got unlucky. And yet most of us treat the two the same way: we shrug, we rerun, we move on.

Most teams know they have flaky tests. Far fewer know what they cost. Here is a way of finding out.

Why Flaky Tests Survive

Nobody keeps a flaky test on purpose. A build goes red, you recognise the usual suspect, you hit retry, it comes back green, you carry on with your day.

The problem is what those decisions add up to. Atlassian published figures in December 2025: flakiness was behind up to 21% of master build failures in their Jira Frontend repo, around 15% in the backend, and reruns cost more than 150,000 developer hours a year. Microsoft Research put the flaky share of their CI test failures at 13%.

Those are organisations with dedicated build infrastructure teams. If they’re bleeding that much time, your number is probably worse.

The Four Costs

Rerun cost. CI minutes spent on repeat runs, multiplied by your CI rate. It’s the easiest figure and usually the smallest, but calculate it first: a finance team understands it instantly, and it opens the door for the bigger numbers.

Investigation cost. Count the failures someone triaged that turned out not to be bugs. Multiply by average triage time, then by a loaded engineer hour. This normally lands at several times the rerun cost, and it’s the figure that moves a planning meeting.

Escaped defect exposure. Once a suite has cried wolf often enough, engineers rerun instead of investigating, and eventually a real bug rides through as noise. You can’t measure this cleanly, but you can count how many failures last quarter were closed without anyone ever opening them.

Lost trust. No formula for this one. It’s the day your team stops reading the test report. Name it anyway; it’s what makes the other three urgent.

Running The Audit

Two weeks is enough:

  1. Turn on per-test run history. Most CI platforms log this by default.
  2. For two weeks, tag every failure: real bug, flaky, or unknown.
  3. Count reruns and pull requests affected per test.
  4. Fill in the four costs above.
  5. Rank by pull requests affected, not by how often a test fails.

In one week of platform data, ten organisations accounted for 82% of every flaky action recorded, and one for 32%. Flakiness concentrates, so your average tells you little about where to start.

A test that fails rarely but blocks your main branch every single time costs far more than one failing constantly in a suite nobody gates on. It’s the same instinct behind risk-based testing, just applied to maintenance rather than coverage.

What You’ll Find

Root causes cluster tightly. Analysing open-source Java projects, Luo et al. attributed roughly 45% of flaky tests to async wait, 20% to concurrency and 12% to test order dependency. The same paper found 54% of async-wait flakes were fixed by awaiting a response instead of a fixed timeout, and 74% of order-dependency flakes by cleaning shared state between runs.

That work underweights one category, because browsers have changed since 2014: selector drift. The test is logically correct, but the element it looks for has been renamed, moved or refactored away. Keep it separate: nothing is racing; it isn’t non-determinism at all. It’s maintenance debt in a reliability costume, and it responds to different treatment.

There’s a second thing that paper can’t see, because it isn’t a property of the test. One parameterised test appeared broadly unreliable until split by data fixture: Belgium failed 56% of runs, Portugal 50%, the Netherlands 40%, France 0%. Three fixtures had incomplete data, and the metric pooled them with the working ones. Before you classify a flaky test, check that it’s one test.

Fix, Delete, or Replace

Fix when the cause is genuine non-determinism in your own code: race conditions, shared state, a teardown that doesn’t mirror its setup. These are bugs in your tests, and they earn engineering time.

Delete when the test covers a path nobody uses, or duplicates coverage you already have. Most suites should be smaller, and deleting is a legitimate outcome of an audit, not an admission of failure.

Replace when the cause is selector drift. Repairing a brittle selector buys you about six weeks before the next one breaks. If a test falls over every time the interface is refactored, the fault lies in how it finds elements rather than in what it asserts, which is the point to look at test execution that adapts when the UI changes, rather than repairing locators by hand.

Quarantine buys time; it doesn’t fix anything, so treat it as a waiting room with a discharge date. And be suspicious of timeout adjustments: Lam et al. found developers who believed they’d fixed flaky tests by raising time values had often, when measured, changed nothing at all.

Re-Measure in 30 Days

One caveat: flakiness rate depends on where you measured, not only on the tests. In the same dataset, actions run from CI were flaky 0.8% of the time, scheduled batch runs 2.7%, and interactive debug runs 3.5%. Same tests, same applications. Record which context your baseline came from, or a suite that looks worse after a fix may only have been measured somewhere noisier.

Track three numbers: rerun rate, pull requests affected, and the share of investigated failures that turned out to be real. That third one is the honest signal. If it isn’t climbing, the audit hasn’t worked yet, and saying so beats declaring victory. If you’re building out QA metrics more broadly, flake rate belongs alongside build time and change failure rate, not in a separate report nobody opens.

The goal was never zero flaky tests. It’s a suite whose failures you believe.

Sources cited:

  • Atlassian Engineering, Taming Test Flakiness (8 December 2025)
  • Luo et al., An Empirical Analysis of Flaky Tests, FSE 2014: https://mir.cs.illinois.edu/marinov/publications/LuoETAL14FlakyTestsAnalysis.pdf
  • Lam et al., ICSE 2020: https://doi.org/10.1145/3377811.3381749

Author

Karim Jouini, CEO at Thunders

Karim Jouini is the co-founder and CEO of Thunders, an AI-native testing platform whose agents write, run, and maintain test suites. He wrote and sold his first software at 16, studied software engineering and AI at INSA Toulouse and the University of Western Ontario, then spent seven years at Microsoft, where he first got close to testing and quality. In 2014 he co-founded Expensya, scaled it past 700,000 users across 100 countries, and sold it to Medius in 2023 for over $100 million. He founded Thunders in 2025 to rebuild software testing around AI agents rather than brittle scripts. He is a Forbes Technology Council member and one of France’s most active business angels, ranked fourth on the 2025 Angelsquare and Challenges list with investments in 26 startups.

Thunders were exhibitors at AutomationSTAR Conference EXPO 2026. Join us in Antwerp 4-5th November 2026.

· Categorized: AutomationSTAR · Tagged: 2026, EXPO

Aug 24 2026

Why AI Coding Agents Need a Way to Verify Their Own Work

AI coding agents can now build entire features from a single prompt. Tools like Claude Code, Codex CLI, and Cursor write code quickly and confidently. But there is a gap in this workflow that testers will recognize immediately: writing code and verifying that it works are two different disciplines.

The Verification Gap

Large language models are non-deterministic. The same prompt can produce different output on different runs, and agents occasionally hallucinate behavior that does not exist. One common workaround is asking the agent to review its own work, but self-verification in a loop is expensive and circular. An agent grading its own homework is not evidence.

What is missing is what testers have always insisted on: an independent, repeatable check against the real system. For web applications, that means opening an actual browser, executing the user journey step by step, and returning a clear pass or fail.

Closing the Gap from the Terminal

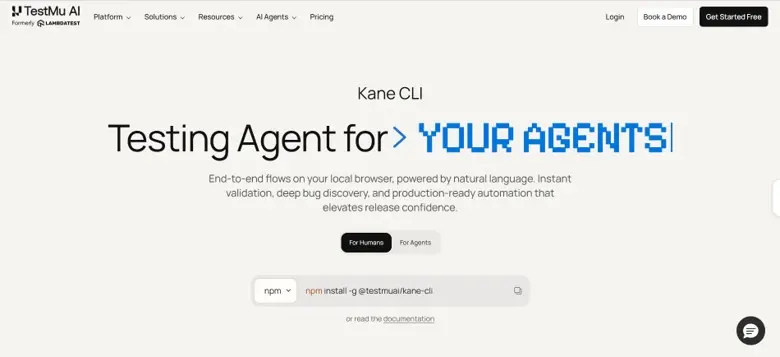
This is the problem Kane CLI, from TestMu AI, sets out to solve. It brings the KaneAI testing agent into the terminal, where both developers and coding agents already work. You describe a flow in natural language, such as a login, a form validation, or a checkout journey. Kane CLI runs it in a local Chrome browser and returns a deterministic result with a shareable evidence link containing video and a step trace.

The design choices reflect sound testing principles:

  • Deterministic results. Every run ends in a binary pass or fail, backed by a real browser execution rather than the agent’s own opinion.
  • Human-realistic actions. It only performs actions a real user could take inside the viewport. It never injects custom JavaScript to bypass validations and force a pass.
  • Resilient, repeatable tests. Vision-based waiting detects loaders and animations, and self-healing absorbs cosmetic UI changes, so tests survive across runs and environments.
  • Human-in-the-loop. When a flow hits an OTP or CAPTCHA, it pauses, asks a human to complete that step, and continues.

Where This Fits

For agents, verification happens through a structured agent mode: the coding agent calls Kane CLI, reads the machine-readable result, and decides whether to fix, continue, or escalate to a human. For teams, flows can export to native Playwright code and run headlessly in CI/CD pipelines.

The broader lesson holds regardless of tooling: as agents take on more of the building, independent validation becomes more important, not less. Verification, like testing itself, works best when it is decoupled from the thing being verified.

Author

Mudit Singh Co-Founder at TestMu AI

Mudit Singh, Co-Founder and Head of Growth at TestMu AI (Formerly LambdaTest), is a dynamic force in the world of software innovation. With over a decade of expertise in building and scaling remarkable software products, Mudit has played a pivotal role in TestMu AI’s mission to transform the software testing landscape.

His strategic vision is centered around shifting testing ecosystems to the cloud, optimizing efficiency, and driving tangible business outcomes. Known for his hands-on approach to product development, Mudit thrives on creating solutions that deliver immense value to customers. When he’s not pushing the boundaries of product and growth, Mudit enjoys exploring the intersection of technology and business trends, always staying ahead of the curve.

TestMu AI are an AutomationSTAR 2026 exhibitor. Join us in Antwerp 4-5 Nov 2026.

· Categorized: AutomationSTAR · Tagged: 2026, EXPO

  • « Go to Previous Page
  • Page 1
  • Page 2
  • Page 3
  • Go to Next Page »

Copyright © 2026 · Impressum · Privacy · T&C

part of the