• Skip to main content
Don't miss out - Join us 4-5 Nov | Book Now!

AutomationSTAR

Test Automation Conference Europe

  • Programme
    • AutomationSTAR Team
    • 2026 programme
  • Attend
    • Why Attend
    • Volunteer
    • Location
    • Get approval
    • Bring your Team
    • 2025 Gallery
    • Testimonials
    • Community Hub
  • Exhibit
    • Partner Opportunities
    • Download EXPO Brochure
  • About Us
    • FAQ
    • Blog
    • Test Automation Patterns Wiki
    • Code of Conduct
    • Contact Us
  • Tickets

test automation

Oct 14 2026

Business Process Assurance: Why Passing Tests Isn’t the Same as a Working Business

Business process assurance (BPA) validates whether an entire cross-system business workflow, such as order to cash or procure to pay, still works end to end after a change, rather than whether individual test scripts passed. It matters most in ERP environments like Dynamics 365, SAP, and Oracle Fusion, where upgrades, transports, and quarterly patches introduce risk on a fixed schedule.
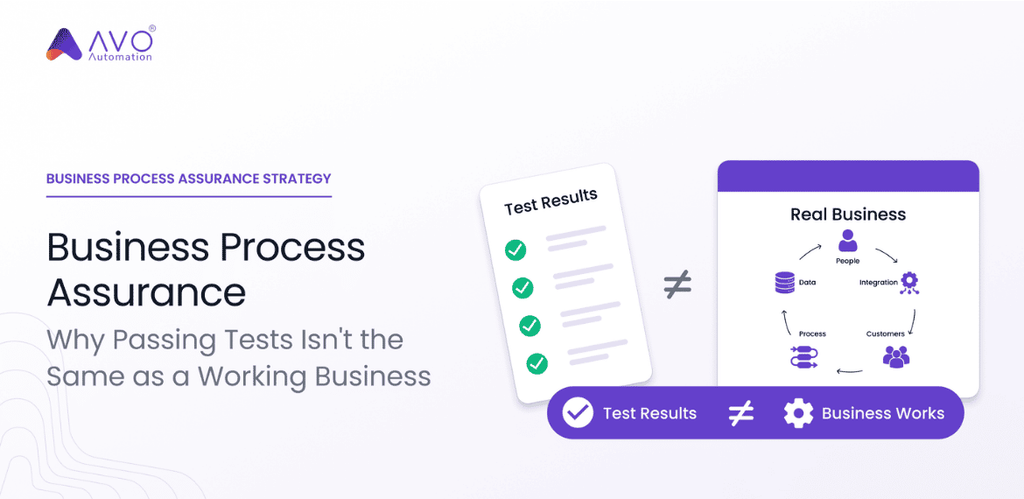
Every business runs on processes that cross multiple systems: order to cash, procure to pay, hire to retire, record to report. When a system changes, whether it’s an ERP release wave, a cloud patch, or a new integration, the question that matters isn’t whether the individual test scripts passed. It’s whether the business process still works end to end, in production, under real conditions.

Business process assurance exists to answer that question. This guide covers what business process assurance (BPA) is, how it differs from testing individual applications, where manual approaches break down, and what a no-code, AI-assisted approach to business process assurance looks like for Dynamics 365, SAP, and Oracle Fusion environments in 2026.

Key Takeaways

  1. Business process assurance validates whether an entire cross-system workflow still works after a change, not just whether individual scripts passed. Passing tests and a working business process are not the same thing.
  2. Manual BPA does not scale against today’s release cadence. Dynamics 365 release upgrades, SAP transport changes, and Oracle Fusion quarterly patches all introduce risk on a schedule that manual regression cannot keep up with.
  3. Prioritize test cases that are high-frequency, business-critical, cross-system, and reasonably stable. Automating everything equally is not a strategy.
  4. No-code business process assurance lets IT directors, ERP project managers, functional consultants, and business analysts build and maintain automation directly, without depending on developers for every change.
  5. Business-Aware, Accountable AI extends BPA beyond execution speed. It understands process dependencies and business risk, and keeps every recommendation explainable and subject to human approval, so testing outcomes tie back to release confidence rather than pass or fail counts.

What Is Business Process Assurance?

Business process assurance validates that integrated systems and workflows function correctly together, not just individually. A typical enterprise business process depends on several components working in concert:

  • Applications: The ERP, CRM, and enterprise systems that run the process, such as Dynamics 365, SAP, or Oracle Fusion.
  • Databases: The systems storing the transactional and master data the process depends on.
  • User interfaces: The screens through which business users and functional teams interact with the process.
  • Integration points: The connections between systems, such as an ERP passing data to a CRM or a payroll provider.
  • Workflows: The sequence of steps, approvals, and handoffs that make up the end-to-end process.

In a software context, business process assurance looks at the same problem from inside the application layer: validating that modules, APIs, user interfaces, and databases interact correctly to support the business outcome the process was built for. The goal in both cases is the same. BPA confirms that a business-critical workflow, such as order to cash or procure to pay, still holds up end to end after a change, by simulating real operating conditions rather than testing each screen or module in isolation.

Why Business Process Assurance Is Different in ERP Environments

Generic business process assurance guidance treats every application the same way. In practice, the applications that carry the most business risk today are ERP systems, and each one introduces risk on its own schedule:

  • Microsoft Dynamics 365: Twice-yearly upgrades plus continuous updates mean Finance, Supply Chain, and HR processes are exposed to change constantly. Microsoft has confirmed that the Regression Suite Automation Tool (RSAT) reaches end of support on May 15, 2027, after which there will be no further bug fixes or maintenance. Teams still relying on RSAT for D365 regression coverage need a migration plan well before that date.
  • SAP ECC and S/4HANA: SAP’s mainstream maintenance for ECC 6.0 (Enhancement Packages 6 through 8) ends December 31, 2027; support for earlier enhancement packages (0 through 5) already ended in December 2025. Either deadline pushes organizations through S/4HANA migrations at the same time they need to keep Order-to-Cash and Procure-to-Pay processes running without disruption.
  • Oracle Fusion: Quarterly patch cycles mean Finance, HCM, and Supply Chain configurations are retested four times a year at minimum, with FlexField and configuration changes carrying real risk of silently corrupting financial reporting if they go unvalidated.

None of these deadlines are optional or negotiable on the vendor’s side. They are the reason business process assurance has moved from a periodic IT activity to a continuous, business-critical discipline.

Manual vs. Automated Business Process Assurance

AspectManual BPAAutomated BPA
Execution speedSlow, dependent on human effortFast, executes on demand
AccuracyProne to human errorConsistent, repeatable execution
Resource requirementRequires ongoing human resourcesRequires upfront setup, less ongoing effort
CostHigher ongoing labor costHigher initial investment, lower ongoing cost
ScalabilityDifficult to scale across company codes or business unitsScales through reusable, parameterized automation
MaintenanceManual and time-consumingSelf-healing automation adapts to UI and workflow changes
Business risk visibilitySurfaces after the fact, often after go-liveContinuous, flags risk before release

Common Business Process Assurance Challenges

BPA runs into the same obstacles in most enterprise environments:

  1. Complexity of business processes. A single process like Order to Cash can span CRM, ERP, logistics, and finance systems. Every integration point is a place where a change in one system can silently break a connected process.
  2. Resource constraints. Manual regression testing pulls functional consultants, ERP project managers, and business analysts away from higher-value work like exception handling and production readiness, every single release cycle.
  3. Constant change. Upgrades, transport changes, and quarterly patches mean test cases go stale quickly, and testing environments themselves can drift out of sync with production.

How to Build a Business Process Assurance Strategy

A working BPA strategy addresses these challenges directly:

  • Automate with intent, not everywhere. Prioritize test cases that are high-frequency, business-critical, cross-system, and relatively stable. A process that runs every sprint and touches revenue is worth automating first. A rarely used screen with a cosmetic UI change is not.
  • Validate end to end, not screen by screen. Cover the full path a transaction takes, from creation through every downstream system it touches, so a defect surfaces before it reaches production rather than after.
  • Build in regression testing as a standing practice. Every release, transport, or patch should trigger a regression pass against the business-critical processes it could affect, not a one-time test at go-live.
  • Design for reuse across company codes and business units. Parameterized automation that runs the same validated process against different datasets scales without multiplying the number of automation assets a team has to maintain.
  • Measure business risk, not just pass and fail counts. A dashboard showing 95% of tests passed doesn’t tell you whether the 5% that failed sits inside a revenue-critical workflow. Tie testing outcomes back to which business processes are actually at risk.

What to Look for in Business Process Assurance Software

Choosing the right platform comes down to a few criteria that matter in ERP environments specifically:

  1. No-code test creation. IT directors, ERP project managers, functional consultants, and business analysts should be able to build and maintain automation directly, without writing code or waiting on a developer for every change.
  2. Business-Aware, Accountable AI. AI that understands business process dependencies and prioritizes validation based on business risk, not just screen coverage, with every recommendation explainable and subject to human approval.
  3. End-to-end test coverage. The ability to validate a process from start to finish across every system it touches, not just the primary application.
  4. Cross-platform compatibility. Testing across web, desktop, ERP, and mainframe environments, spanning a wide range of technologies from a single platform.
  5. Parallel and distributed execution. Running tests concurrently to cut regression cycle time, especially valuable when the same process needs to be validated across multiple company codes or business units.
  6. CI/CD integration. Fitting into existing DevOps pipelines so testing runs continuously as changes are deployed, rather than as a separate manual gate.

How Avo Assure Approaches Business Process Assurance

Avo Assure goes beyond test automation to Enterprise Business Process Assurance. With no-code test creation, Business-Aware, Accountable AI, and end-to-end test coverage, Avo Assure helps teams validate business processes across Dynamics 365, SAP, Oracle, and every connected system, without relying on developers.

In practice, that looks like Synergy Marine Group, one of the world’s largest ship management companies, validating standardized SAP business processes across multiple company codes and connected applications, including Microsoft Dynamics 365 Business Central and SAP Concur. Working with Accenture, the team reduced manual regression effort by 90% and reached approximately 80% automation coverage of planned business scenarios, using reusable automation instead of building separate scripts for every company code.

Read the full Synergy Marine Group and Accenture case study for the complete breakdown of the engagement and its results.

Across enterprise deployments generally, Avo Assure customers report:

  • 10x faster time to market with intelligent, end-to-end test automation
  • 90%+ business process automation coverage
  • 85% less maintenance effort, through self-healing automation
  • 80% reduction in effort required to create and execute tests

The right business process assurance approach determines whether a release goes smoothly or becomes a production incident.

See how Avo Assure helps you move beyond test automation to business process assurance and book a demo to get started.

Frequently Asked Questions:

What is business process assurance?

Business process assurance (BPA) validates that an integrated business workflow, such as order to cash or procure to pay, works correctly end to end across every system it touches, rather than testing each application or screen in isolation.

How is business process assurance different from regular software testing?

Regular software testing typically validates a single application or module. Business process assurance validates the full workflow a business depends on, which often spans multiple systems, such as an ERP, a CRM, and a payroll provider, and confirms the process still functions correctly as a whole after a change.

Why does business process assurance matter more in ERP environments?

ERP systems like Dynamics 365, SAP, and Oracle Fusion change on a fixed vendor schedule, whether through upgrades, transport changes, or quarterly patches. Each change carries a real chance of breaking a business-critical process like financial close or order fulfillment, which makes continuous validation a business necessity rather than a periodic IT task.

Can business processes assurance be automated without a dedicated QA team?

Yes. No-code platforms let functional consultants, business analysts, and ERP project managers build and maintain business process test directly, without relying on developers or ongoing support from implementation partners.

What is the difference between test automation and business process assurance?

Test automation confirms that a script ran and passed. Business process assurance goes further: it confirms that the underlying business process, such as Order to Cash, still works correctly end to end after a change, and ties that outcome to business risk rather than a pass or fail count alone.

How often should business-critical processes be regression tested?

Business-critical processes should be regression tested every release cycle, and again after any configuration, transport, or patch change, since ERP environments on continuous release schedules introduce risk multiple times a year, not just at major upgrades.

Does business process assurance cover processes that span multiple ERP or enterprise systems?

Yes. Processes like Order to Cash or Hire to Retire rarely stay inside a single system. Business process assurance should validate the full cross-system path, including CRM, logistics, finance, and HCM platforms connected to the core ERP.

What should I look for in business process assurance software?

Look for no-code test creation, Business-Aware AI that prioritizes validation by business risk rather than screen count, end-to-end coverage across every system in the process, and the ability to reuse automation across company codes or business units without rebuilding it each time.

Avo Automation are Exhibitors at AutomationSTAR Conference EXPO 2026. Join us in Antwerp 4-5th November 2026.
· Categorized: test automation · Tagged: 2026, EXPO

Oct 09 2026

A little wild, a little wonderful: your team’s Antwerp mini-guide

A railway station that looks like a cathedral, penguins next door, and an old town best explored without too much of a plan. AutomationSTAR comes to Antwerp on 4–5 November with two days of test automation and AI in testing, held a minute’s walk from the train.

Bring your team and you’ll cover more sessions, bring home more ideas, and save up to 25% on tickets. Plus, leave a little space for new experiences.

Here’s how to make the most of the city between talks.

Look up – you’ve arrived

At Antwerp Central, resist the urge to follow the crowd straight to the exit. Often called the ‘railway cathedral’, it lives up to the name. Stop under the great domed hall, take in the marble and gilt, and gather everyone for a team photo. A Room with a ZOO, our conference venue, is just a minute’s walk away. Getting the team from train to conference is the easy part. Persuading everyone to stop taking pictures might take longer.

Meet the neighbours

Not every conference has penguins next door…

Antwerp ZOO is one of the oldest in the world, and its 19th-century gardens and grand animal houses make a fine first afternoon if you arrive a day early. It’s an easy way to stretch your legs and catch up before the sessions start. It’s also a good escape between talks when your brain needs a breather. November days are short, so check closing times and go early.

Split up, swap notes

Wednesday morning is where a team really pays off. At 9am, seven hands-on tutorials start at the same time. Someone builds and breaks an AI testing agent in the AI Testing Dojo, someone else gets to grips with a scalable Playwright framework, and a third person explores agentic mobile automation. On your own you get to choose one. With a team, you can cover them all.

The keynotes give everyone something to discuss over lunch, and deep dives are already starting to book out – so the sooner your team is registered, the more choice you’ll have.

book tickets

Let the old town lead

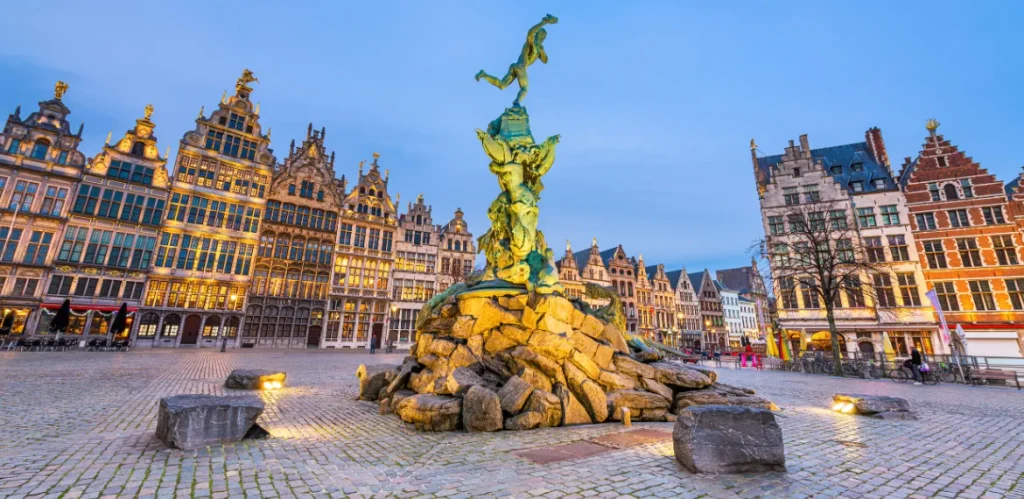
Make for Grote Markt, where ornate guild houses that lean over the square reward a slow look upwards. The Brabo fountain tells the city’s founding legend: a giant, a severed hand and a hero with a good throwing arm. Then follow the cobbled streets, take a turn that looks interesting and see where you end up.

Let a different colleague choose each stop: a coffee here, a warm waffle there, a table somewhere inviting. Leave enough room for the conversation to wander too.

Raise a bolleke

If your team enjoys a Belgian beer, book the De Koninck brewery experience to learn how Antwerp’s favourite beer is made. Then order a bolleke, as the locals call it after its round glass. The site has food shops and places to eat, so you can easily stay for dinner. Book ahead for groups.

Or keep it simple: after Wednesday’s EXPO party, reserve a long table in the old town and let the day’s talks carry on over dinner. Expect at least one heated debate about flaky tests.

Follow the river to a fortress

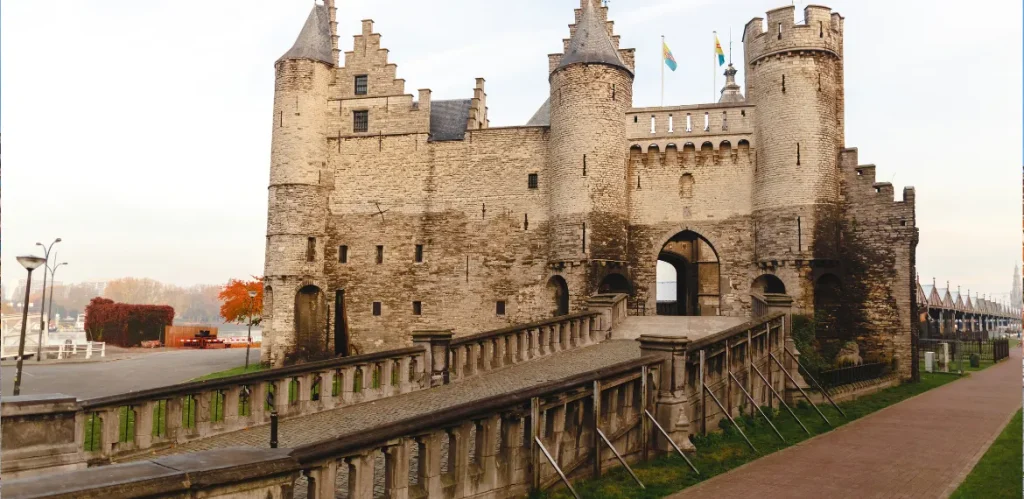
A medieval fortress on your evening wander? Antwerp has that covered. Head towards the Scheldt and you’ll find Het Steen, the city’s oldest surviving building. Stop for a photo, take in the river views and give yourselves a little time before dinner. A few centuries of history makes a good change from talking about your next sprint.

Make room for chocolate

For a team outing with broad appeal, put Chocolate Nation on the list. Its interactive museum explores the world of Belgian chocolate, making it a tempting stop for a spare afternoon — especially if November sends you indoors.

Afterwards, seek out a chocolate shop together and compare your choices. Anything that makes it back to the office is a bonus.

Bring something back together

Attending AutomationSTAR as a team means you’ll come home with more sessions covered, more practical takeaways and a shared plan to act on them. Antwerp adds the long dinners, the detours and the conversations you rarely find time for during a normal working week. And it costs less:

  • Team of 3–4: 15% off
  • Team of 5–9: 20% off
  • Team of 10: 25% off, just €1,050 per person

Bring your colleagues, comfortable shoes, and a little curiosity. Antwerp will take care of the detours! You can find out more about hotels and getting here on our Location page.

Your next team trip is less than a month away! Book your tickets now.

book tickets

· Categorized: test automation, Uncategorized · Tagged: 2026

Sep 17 2026

The Skills I Learned and the Ones That Got Away

Ahead of her AutomationSTAR Deep Dive, Close Encounters with Systems, Rachel Kibler reflects on the skills that shaped her testing career—and how systems thinking gave her a name for what she was already doing.

I started my career by diving headfirst into the context-driven testing community, forming some very strong opinions along the way. I look back at my dogmatism and wonder why I was so convinced that I, a baby tester, was right just because I was parroting something persuasive that resonated with me.

I found my way to conferences, which broadened my horizons and showed me that yes, everyone thinks in terms of context, and the arguments that we have within our testing community can be tiresome, worn-out, and ultimately unhelpful, even harmful when they gatekeep and manufacture heightened emotions around who’s doing testing “the right way”.

Ten years in, I hold a lot of my strong beliefs still, but considerably more loosely, and I’ve become much more understanding of everyone’s journey. Turns out, not everyone needs to do things the way I do them!

In addition to my attitude shift, I found that the skills I learned early on formed a lot of what I care about and still think about. And that these skills that I value turned out to be systems thinking before I had the words for it. Elisabeth Hendrickson’s book, Explore It!, was massively influential in learning how to create test charters and organize my mental models, as was Janet Gregory and Lisa Crispin’s Agile Testing in thinking strategically about how to deliver quickly and not be a bottleneck.

James Whittaker’s How to Break Software was one of the earliest I read, and though he does spend a lot of time on printer testing, the idea of creativity in your testing by shaking up the machine (sometimes literally) was helpful. And doing the Black Box Software Testing foundations course by Cem Kaner and Rebecca Fiedler through the Association for Software Testing played a huge role in shaping my skills too.

Because of those influences, I learned to think about software in creative ways, to not trust what someone says the software does and does not do, and to spend time following my gut instincts about where things could be broken, largely at the boundaries of the software and the boundaries of our understanding of the software.

I learned how to communicate well with my developers and at the right time. I learned how to advocate for my bugs, and hopefully for the user. I learned how to identify risk and to bring people together for conversations about what matters and what quality is for our products, creating feedback loops and shared mental models. These skills felt good to me, they felt right, and they enabled a solid career with good delivery of software.

Some testing skills eluded me though. Writing extensive documentation has never been my strong suit, and though I do strongly believe that test management systems are a kindness and should be a system of record for our software, writing steps down in depth has always felt daunting and overwhelming to start with. But documentation does make our system legible to others, modeling what we understand to be true. I also never really got a handle on what my automation should look like when it’s at its best, when it’s giving the feedback on the system in the right place.

AI changed the game for me, enabling me to pay more attention to the “what” and the “why” of automation rather than the “how” that had been so much of the concern of past me. However, thinking about documentation and automation in terms of systems may be the thing that drives both of these forward for me.

For AutomationSTAR in Antwerp this November, I get to do a deep dive into systems thinking itself. I’ll give a brief overview of the concepts in systems thinking before we dive deeper into time delays and other less intuitive things, pulling heavily from the new work of Elisabeth Hendrickson and Joel Tosi (their book, Signals & Levers, releases on September 22nd, 2026) as well as the work of Donella Meadows (Thinking in Systems: A Primer) and many others. Learning from Elisabeth Hendrickson’s book at the beginning of my testing career and now from her new book with Joel Tosi seems fitting.

I didn’t invent any of this, it’s been around for a long time, but it’s more relevant than ever right now. Systems are becoming more and more complicated as we throw AI into the mix for both the software itself and the processes around it. Feedback loops are getting longer and stranger, and the levers to pull are moving. Testers talk about systems in daily work, but perhaps without the structured framework to make the conversation’s importance clear. Systems thinking gave me language for the things I learned to do by instinct or by mimicry, and I’m excited to pass that on so you can talk about the things you already do and care about in terms of systems.

Rachel Kibler is speaking at AutomationSTAR – check out her Deep Dive and book your tickets.

· Categorized: test automation, Uncategorized · Tagged: 2026

Jul 16 2026

We analysed every AutomationSTAR 2026 submission. Here’s what test automation will look like in 3 years

This year’s Conference theme of “Future Skills” is not just a theme – it is being echoed by the data we are receiving for the Call for Speakers on the roles of the future and the skills that will define them.

Curious about how your job will look like in 3 years?

Instead of reading job advertisements from the past – our speakers are tackling the problems they face today with the tools they use and are frantically searching for the necessary skills to keep their job.

The AutomationSTAR Call for Speakers this year is even more valuable for those who work in test automation and quality in general. This year’s Programme Committee analysed all the submissions for the opportunity to speak at this event, and the result of such analysis paints a picture of what working in test automation will look like in 3 years from now.

If you work in quality this is THE event you MUST attend in 2026. Here is why.

book tickets

The topic map has been redrawn

Three years ago, our topic categories were organised around technologies: web, API, mobile, performance. Look at where submissions landed this year.

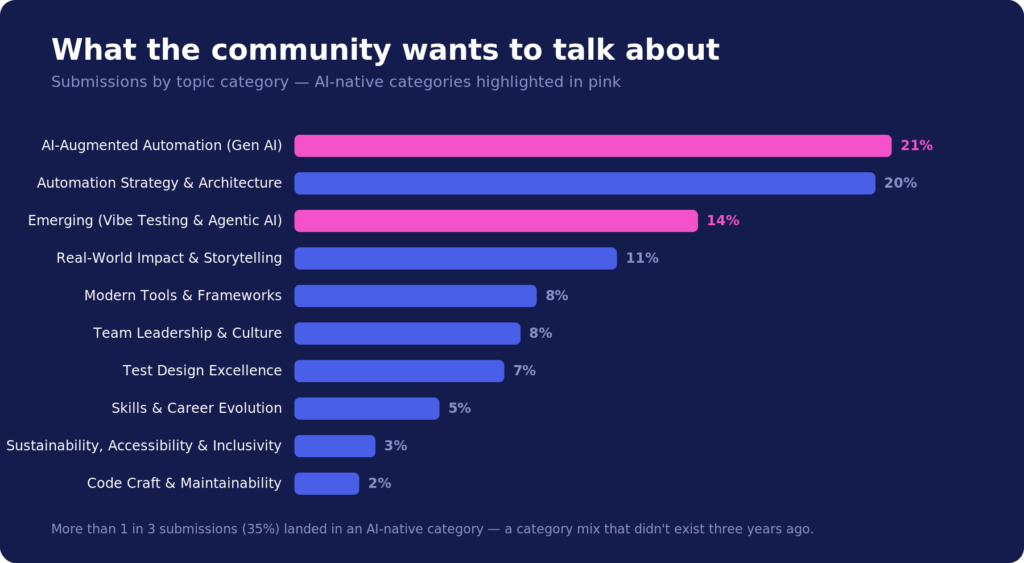
Of the submissions we received 35% fell into what we’re calling ‘AI-native’ categories of work such as ‘vibe testing’, ‘agentic AI’ and Gen AI-augmented automation. These categories have naturally evolved in the community and were not created by us for marketing purposes and have since taken off.

Meanwhile the category of Automation Strategy & Architecture retained its position as one of the most popular at 20%. Given the rapid evolution of the tools available for automation this category will continue to be relevant as someone needs to ensure that the automation is working effectively.

Code Craft & Maintainability scored the lowest with 2% of all submitted topics. As we were really excited to start to dive into the many questions and topics how to build something new in the first place, the community is clearly more interested in just building something new instead of taking care of something that has already been built. This is a gap one should be aware of.

The AI wave, measured

“AI is everywhere” is easy to say. Here’s what it looks like in numbers.

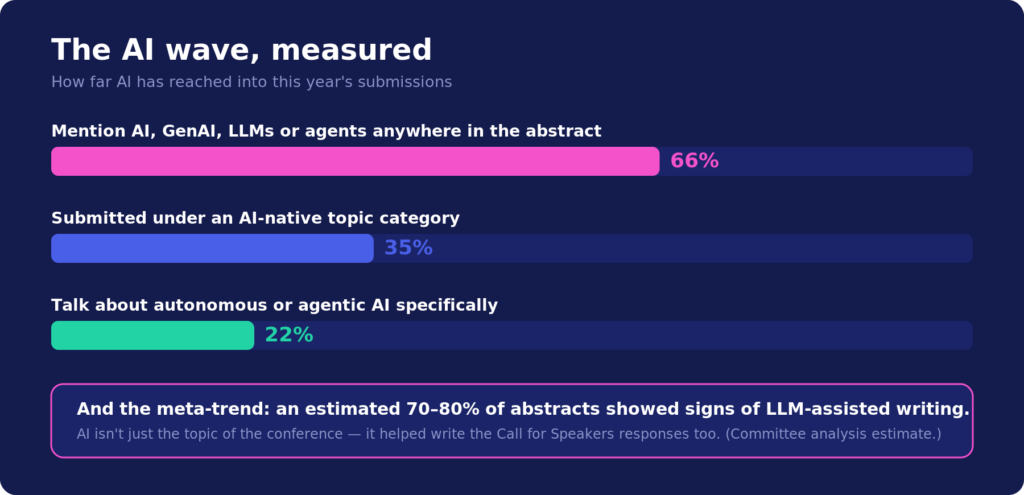
About two-thirds of the abstracts in all areas (design of tests, leadership, etc.) referred to AI, LLMs or agents. Autonomous and agentic AI was mentioned in 22% of the abstracts. On average, the abstracts focusing on AI, LLMs or agents received higher ratings from the committees than the abstracts that did not focus on these topics.

Additional to the former findings, the analysis furthermore detected a meta-trend within the abstracts under review: roughly 70–80% of the abstracts were written with the support of an LLM.

As before, however, when every single abstract was written to perfection using an LLM, the only remaining difference would be the authors’ experience. And this is exactly what the reviewers are trying to find – in line with this year’s review theme.

The vocabulary shift

Perhaps the clearest signal of all: count which words the community reaches for.

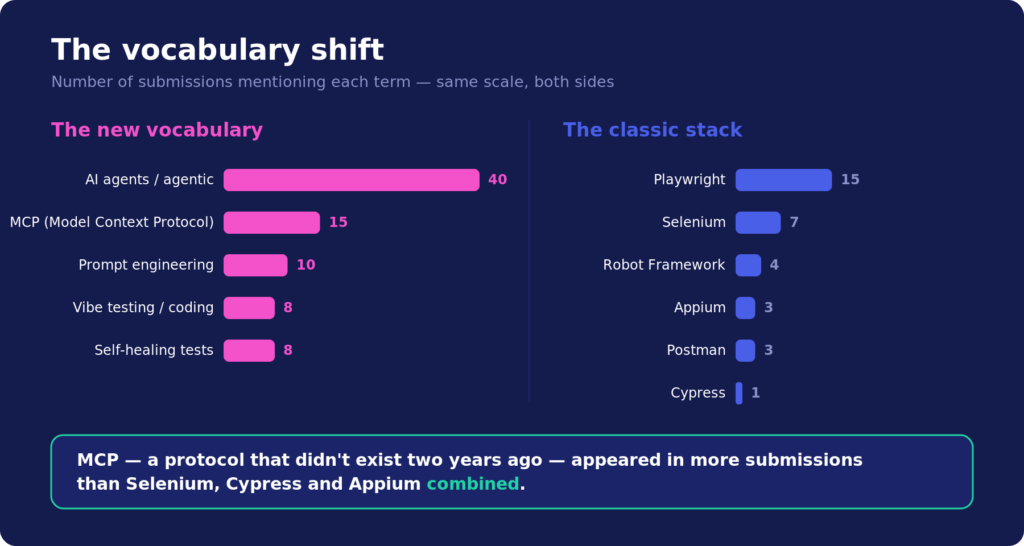
“Agents” and “agentic” were mentioned 40 times. The Model Context Protocol (MCP), for model deployment that was not yet established two years ago, was even mentioned more often than Selenium, Cypress and Appium together. Playwright, the heavyweight automation tool, was even mentioned as often as MCP.

The graph does not mean to suggest that all people have stopped using Selenium and Cypress for running their thousands of test pipelines. Rather, the focus of the test automation discussion has shifted from which test automation framework to use (Selenium, Cypress, Appium, etc.) to how to control, direct, put bounds to, and trust an autonomous test system.

Be in the room for all the important conversations at AutomationSTAR 2026 – book your tickets now.

Future Skills: the theme that chose itself

When we set “Future Skills” as this year’s theme, we wondered if the community would engage with it. They did — but not in the way a skills-matrix would predict.

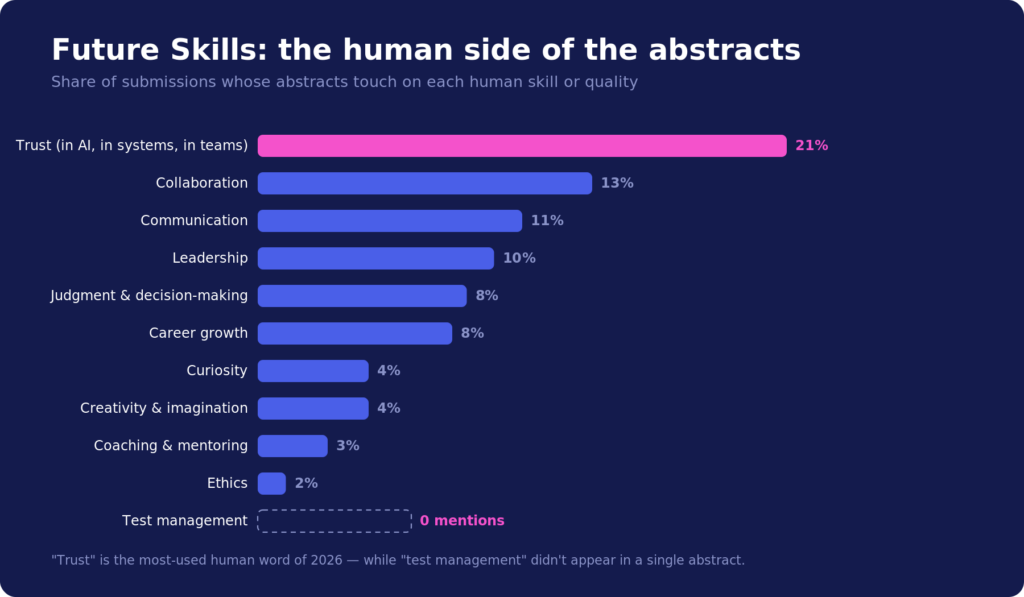
The word that humans keep using in this year’s abstracts is: trust. It appears in 21% of the abstracts. This word is used to discuss the trustworthiness of AI, of different types of of fully autonomous agents, of teams of agents, and of the systems under test by the authors. Also discussed are collaboration, communication, leadership, and judging.

Interesting the term “test management” didn’t make the cut as a keyword in any of the abstracts. What was once a foundational term for a whole conference track a decade ago is now gone from practitioners’ vocabulary and has been replaced with terms that speak to trust, human judgment, and human / AI collaboration.

So here’s the nutshell summary of Future Skills: The mechanical parts of our work are getting covered by automated tools and thus will cease to be our area of work in the future.

What will remain with us, is what makes us human. That is: knowing when the green of your dashboard is only painting it green and thus might be lying to you.

Deciding how much autonomy to give to which kind of autonomous agent. Explaining risks to people who have to make decisions on the basis of that risk.

Fresh stories, seasoned voices

One more finding we loved.

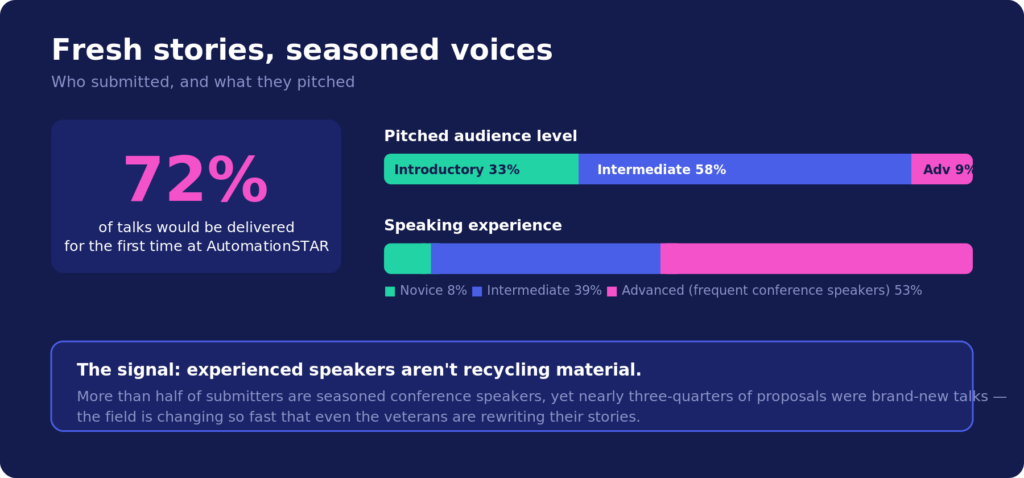
72% of proposed talks will be new to AutomationSTAR 2026. 58% of submitters are experienced conference speakers, yet they are rewriting their stories as the automation field is changing very quickly.

The audience-level mix for the proposed talks is 58% intermediate, 33% introductory, 9% advanced. The field of automation is being reinvented fast, and so there is a point at which everyone is a beginner for that section of the discipline. Hence the community will be presenting talks for this audience.

From everywhere, to Antwerp

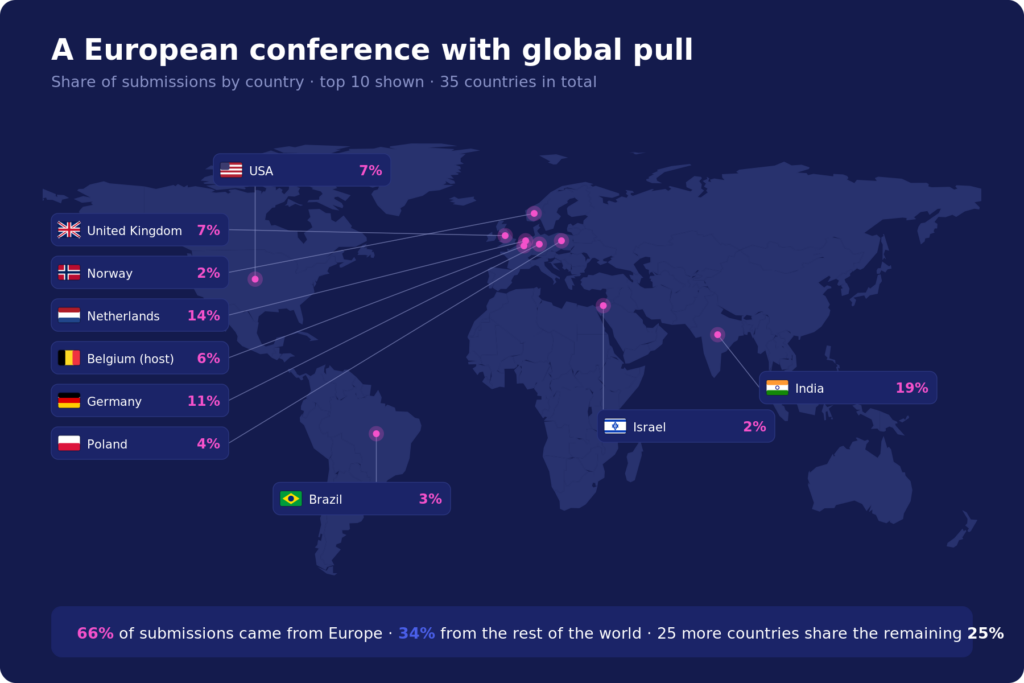
We received submissions from 35 countries around the world with 2/3 of the submissions coming from all over Europe. The country with the most submissions was India followed by submissions from the Americas, the Middle East and Asia-Pacific. The community is asking the same questions in Bangalore, Berlin and Brussels.

What this means for your career

The 2026 program is essentially a translation of everything we have stated: the agentic frontier, the strategy and architecture backbone of the program, actual use cases as opposed to vendor pitches, and a thread of human skills of judgment, trust and communication that no model can ever automate.

Data confirms that our profession will not be replaced by machines. Instead, we will be redefining the work of the next generation of information workers, directing autonomous systems, architecting quality strategy that leverages off these systems, and bringing trust, judgment to the work that machines cannot.

We can get a grip on this work quickly by understanding the work of our peers around the submissions for the 2026 program have been written by the very people redefining our work, our students work, and the work of our clients – two fast-paced days in a room with them is likely to get you and your work ahead quickly – join us in Antwerp in November.

Join us at AutomationSTAR 2026, Antwerp, 4–5 November.

Book tickets

· Categorized: test automation, Uncategorized

Sep 13 2024

Eight recipes to get your testing to the next level

You’re doing well in testing. Your systems and business processes are well covered. Test automation is on track. Your reports are nice, shiny, and green. All is good.

But then you go for a beer with your colleagues.

You discuss your daily work. And, at least in Vienna (Austria), it is traditional (and not uncommon) to open up with friends, share your workday, and even complain in such a setting. You realize there’s still lots to do.

Every morning, failed test cases need to be analyzed and filtered. Some flaky tests are keeping the team busy – they are important tests, but they refuse to stabilize. Changes in product and interfaces are breaking your tests, thus requiring maintenance. The team must refactor and weed out redundant tests and code multiple times.

In short, it seems there is a lot of work to be done.

This article will guide you through some test automation pain points that will likely sound familiar. But every problem also has a solution. Along with the pain points, we’ll also highlight possible approaches to alleviate them. For most of these issues, Nagarro has also developed mature solutions (see our “AI4T“) – but that is not what this article is about.

What’s cooking? 

Innovation is like cooking – it is about listening to feedback and striving to improve by not being afraid to experiment and bravely trying out new things.

We’ve prepared this dish many times – so you need not start from scratch! And to top it off, we’ll even provide a basic recipe to get you started.

== First Recipe ==

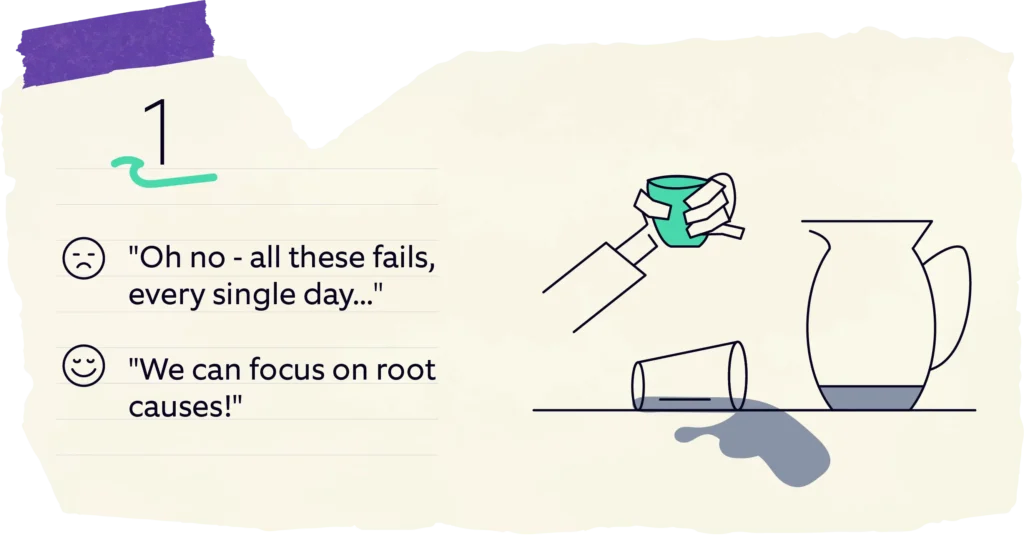
From “Oh no – all these fails, every single day…” to “We can focus on root causes!”

You come into work (be it remotely or in the office). You’re on “nightly run duty.” Some tests in your portfolio have failed.

Step 1: You sit down and start sifting through. After about two hours, you identify seven different root causes and start working on them.

Step 2: Fixing test scripts, fixing environment configurations and logging actual issues.

Wouldn’t it be nice to skip step 1? Let’s say you have 3000 automated system test cases. And about 4% of them fail. That means 120 failed tests to analyze. Each and every day. That’s a lot of work.

But you do have a lot of historical data! Your automated tests and the systems you’re testing produce log files. You need to analyze the root cause – so if you capture it somewhere, you have a “label” to attach to each failed test case.

And that is precisely what you can use to train a Machine Learning algorithm.

So from now on, in the morning, you get a failed test result and a presumed root cause associated with it. This enables you to look in the right places, assign it to a specific team member with special skills, and skip all tests with the same root cause you just fixed. What an effective and efficient, wonderful and mouth-watering prospect, isn’t it?

== Second Recipe ==

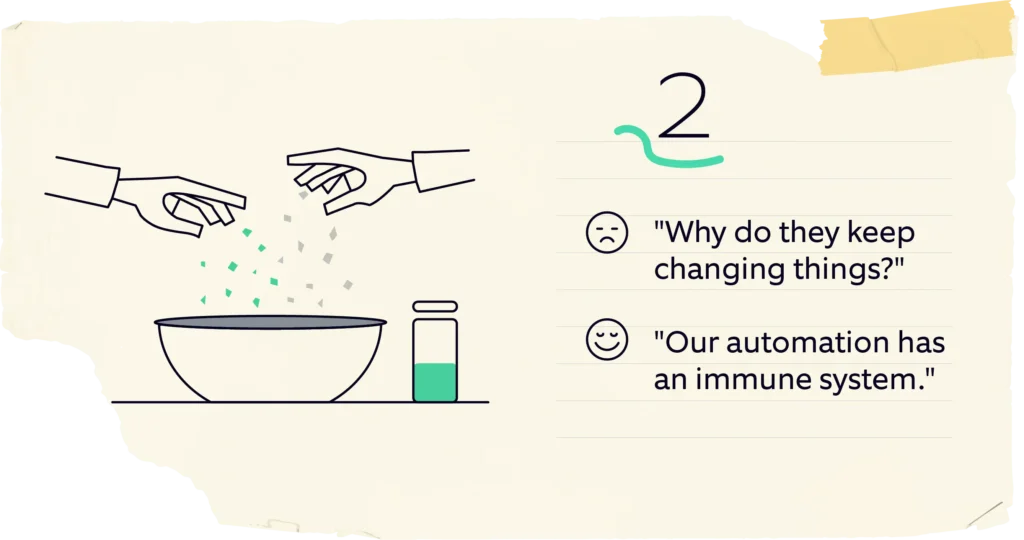
From “Why do they keep changing things?” to “Our automation has an immune system.”

Systems change in an agile world (and even in a “classical” world). A lot. Both on the User Interface side and on the backend. The bulk of a test automation engineer’s time is spent on maintaining tests or changing them along with the product they test.

Now imagine, wouldn‘t it be great if your automation framework could, when some interaction with the system under test fails, check if it is likely an intended change and automatically fix the test?

Let’s say your “OK” button is now called “Confirm”. A human would likely take this change, maybe make a note of it but largely ignore it. It’s most likely they would not fail the test case. But guess what, your test automation might stumble here. And that means:

  • Analyzing the failed test case
  • Validating the change manually (logging in, navigating there etc.)
  • Looking for the respective automation identifiers
  • Changing them to the new values
  • Committing those changes
  • Re-running the test

All this can easily consume about 15 minutes. Just for a trivial change of word-substitution. We do want to know about it, but we don’t want to stop the tests. Imagine if this change is in a key position of your test suite – it could potentially block hundreds of tests from executing!

Now if your framework has some way of, instead of failing, noticing that “OK” and “Confirm” are synonyms, and validate some other technical circumstances to be confident that “Confirm” is the same button as “OK” used to be, it can continue the test.

It can even update the identifier automatically if it is very confident. Of course, it still notifies the engineer of this change, but it is easy for the engineer to take one quick look at the changes and decide whether or not they are “safe”.

== Third Recipe ==

From “AI in testing? That means huge amounts of data, right?” to “We already have all the data we need.”

Machine Learning requires thousands of data points, right? Maybe, even millions?

Yes and no. Let’s take our example from the first delicacy – finding out the root causes for failed test cases based on log files. Since log files are fairly well-structured and deterministic, they are “easy” to learn for an ML algorithm – the usual complexities of human speech are substantially reduced here. This means we can use ML algorithms that are on the simpler side. It also means that we don’t need as much data as we would need for many other use-cases.

Instead of tens of thousands of failed test cases labeled with the root causes, we can get to an excellent starting point with just about 200 cases. We need to ensure they cover most of the root causes we want to target, but it is much less work than you would have expected.

Add to that the fact that test automation already produces a lot of data (execution reports, log files for the automated tests, log files for the systems under test, infrastructure logs, and much more) – which means that you’re already looking at a huge data pool. And we‘ve not even touched production logs as yet.

One can gain many crucial insights through all this data. It is often untapped potential. So take a look at the pain points, take a look at the data you have, and be creative! There is a hidden treasure amidst the ocean of information out there.

== Fourth Recipe ==

From “Synthetic data is too much work, and production data is unpredictable and a legal problem” to “We know and use the patterns in our production data.”

Many companies struggle with test data. On the one hand, synthetic test data is either generated in bulk, making it rather “bland,” or it is manually constructed with a lot of thought and work behind it.

On the other hand, production data can be a headache – it is not only a legal thing (true anonymization is not an easy task) but also something about which you don’t really know what’s in there.

So how about, instead of anonymizing your test data, you use it to replicate entirely synthetic data sets that share the same properties as your production data while adding constellations to cover additional combinations?

Ideally, this is an “explainable AI” in the sense that it learns data types, structures, and patterns in the data from production. But instead of “blindly” generating new data from that, it provides a human-readable rule model of that data. This model can be used to generate as much test data as you need – completely synthetic but sharing all the relevant properties, distributions, and relations with your production data. The model can also be refined to ensure that it suits the test targets, even more, learned rules can be fixed, unnecessary rules can be removed, and new rules can be added.

Now you can generate useful data to your heart’s content!

== Fifth Recipe ==

From “What is our automated test suite doing, actually?” to “I can view our portfolio’s structure at a single glance.”

Test coverage on higher test levels is always a headache. Code coverage often does not tell you anything useful at that level. Traceability to requirements and user stories is nice, but they also don’t really give you a good overview of what the whole portfolio is actually doing.

To get this overview, you have to not only dig through your folder structure but also read loads of text files, be they code or other formats, such as Gherkin.

But wait, there’s a catch here – Each test case, in a keyword-driven or behavior-driven test automation context, consists of reusable test steps at some level, representing an action. It could be a page-object-model-based system, or it could attach to APIs – either way, if our automation is well-structured with some abstraction on its business-relevant actions, the test cases will pretty much consist of a series of those actions, with validations added into that mix.

Now, let’s look at test cases as a “path” through your system, with each action being a step or “node” along the way. If we overlap these paths on all your test cases, we can quickly see the emergence of a graph. This is the “shape” of your test automation portfolio! Just one brief look gives you an idea of what it is doing.

Now we can add more info to it: Which steps have failed in the last execution (problematic color nodes as red)? How many times is a certain action performed during a test run (use a larger font for often-executed test steps)?

These graphs quickly become quite large. But humans are surprisingly and incredibly good at interpreting graphs like this. This now enables you to get a very quick overview and find redundancies, gaps, and other useful insights.

== Sixth Recipe ==

From “We run everything, every single time. Better safe than sorry” to “We pick the right tests, for every change, every time.”

Large automated test portfolios can run for hours, if not for days. Parallelization and optimization can get you very far. But sometimes, resources are limited – be it in systems, data, or even hardware. Running all tests every single time becomes very hard, if not impossible. So you build a reduced set of regression tests or even a smoke-test set for quick results.

But then, every change is different. A reduced test set might ignore highly critical areas for that one change!

So how do you pick tests? How do you cover the most risk, in the current situation, in the shortest time?

Much like cooking a nice dish, there are many aspects that go into such a selection:

  • What has changed in the product?
  • How many people have touched which part of the code and within what timeframe?
  • Which tests are very good at uncovering real issues?
  • Which tests have been run recently? How long does this test take?

Again, you’ll see that most of this data is already available – in your versioning system, in your test reports, and so on. While we still need to discuss “what does ‘risk’ mean for your particular situation?” (a very, very important discussion!), it is likely that you already have most of the data to then rank tests based on this understanding. After that, it‘s just a matter of having this discussion and implementing “intelligent test case selection” in your environment.

== Seventh Recipe ==

From “Nobody dares to touch legacy code” to “We know the risk our code carries.”

Continuing on the topic of “risk,” we noticed something else: After spending a lot of time with a certain codebase, experienced coders get very good at knowing which code changes are dangerous and which are not.

But then, there is always some system-critical code written by a colleague who left many years ago, written many years before that. There is code that came from a vendor who is no longer a partner of the company. There are large shared code-bases that vertically sliced teams are working on, with no one having a full overview of the whole. And there are newer, less experienced colleagues joining up. On top of that, even experienced people make mistakes. Haven’t all of us experienced such scenarios?!

There are many systems to mitigate all this. Some examples are code quality measurements, code coverage measurements, versioning systems, and so on. They tell you what to do, what to fix. But they are not “immediate.” Imagine, you’re changing a line of code – you’re usually not looking up all of these things, or the full history of that line, every single time.

So how about a system that integrates all these data points:

  • Is this line covered by tests?
  • How often has it been changed by how many people in the last two days
  • How complex is it?
  • How many other parts depend on in?

We can also factor in expert opinions by, let’s say, adding an annotation. Then we use all this information to generate a “code risk indicator” and show it next to the class/method/line of code. “0 – change this. This is pretty safe”. “10 – you better think about this and get a second pair of eyes plus a review”. If you click on it, it explains all these points and why this score was given directly in your IDE.

The purpose is not to fix the risk, although it can be used for that too. But the primary objective is to give developers a feeling of the risk that their changes carry, before they make them.

== Eighth Recipe ==

From “Model-based? We don’t have time for that!” to “Models create themselves – and help us.”

Model-based testing has been on many people’s minds for many years. But it seems it never really “took off.” Part of the reason might be the complexity of these models, coupled with the fact that these models need to be built and maintained by experts. Apart from this, while these models are very good at generating many tests, they usually have blind spots around the expected outcomes of these tests.

So in most cases, model-based testing is not regularly applied and still has a lot of potential!

So how can we mitigate these issues? By automatically generating a usable model from the available information. You can use many methods and sources for this, like analysis for requirements documents, analysis of code, dependencies, and so on. The flip side of these methods is that the model is not “independent” of these sources but is an interpretation of their content.

But that does not mean that they can’t be useful.

Think back to our “fifth recipe” – generating a graph from our automated test suite. This is actually a state-transition model of our tests and, by extension, the product we’re testing (because the structure of our tests reflects the usage flow of that product). And it has potential.

We could, for example, mark a series of connected nodes and ask the system to generate basic code to execute these test steps in sequence. They will then be manually completed into a full test case. We could ask the system, “is there a test case connecting these two nodes?” to increase our coverage or “are there two tests that are both covering this path?” to remove redundant tests.

Since this model is not created manually, and since the basis, it is generated from (automated tests) is maintained to be in sync with our product, we do not need to spend any extra time to maintain this model either. And it has a lot of use-cases.

== Our traditional recipe ==

Ingredients:

  • 5 annoying everyday tasks and pains
  • A fridge full of data you already have
  • 1 thumb-sized piece of knowledge about Machine Learning
  • 20g creativity

Instructions:

  • Stir your thoughts, complain about the most annoying things
  • Add creativity, mix well
  • Take the knowledge about ML out of the package
  • Add it to the creative mix, gently stir in the data
  • Bake in the oven at 200°C, for the duration of an MVP
  • While baking, check progress and generated value repeatedly
  • Take out of the oven, let rest for a bit
  • Serve while hot – best served with a garnish of practical experience

Have fun and enjoy this dish!

If you have any questions on the test automation and software testing process improvement, don’t hesitate to contact us at aqt@nagarro.com. 

Download your free infographic with all 8 recipes! 

Author

Thomas Steirer CTO and Lead of the Global Test Automation Practice

Thomas Steirer is CTO and Lead of the Global Test Automation Practice. He has developed numerous automation frameworks and solutions for a variety of industries and technologies. At Nagarro, he supports clients implementing test automation and building scalable and sustainable solutions that add value. He is also passionate about using artificial intelligence to make test automation even more efficient. In his spare time, he teaches at universities in Austria and is an enthusiastic Gameboy musician.

Nagarro was a exhibitor at AutomationSTAR 2024.

· Categorized: AutomationSTAR, test automation · Tagged: 2024, EXPO

  • Page 1
  • Page 2
  • Page 3
  • Page 4
  • Go to Next Page »

Copyright © 2026 · Impressum · Privacy · T&C

part of the